All
Articles 189,109Blog Posts 170,867Tech Tutorials 50,677Research Papers 36,770News 23,152
⚡ AI Lessons
Weaviate Blog
🔍 RAG & Vector Search
1w ago
4-bit Rotational Quantization
4-bit Rotational Quantization in Weaviate 1.39: the SIMD performance work, a centered tier, scaling analysis and a TurboQuant comparison.
Weaviate Blog
🔍 RAG & Vector Search
⚡ AI Lesson
2w ago
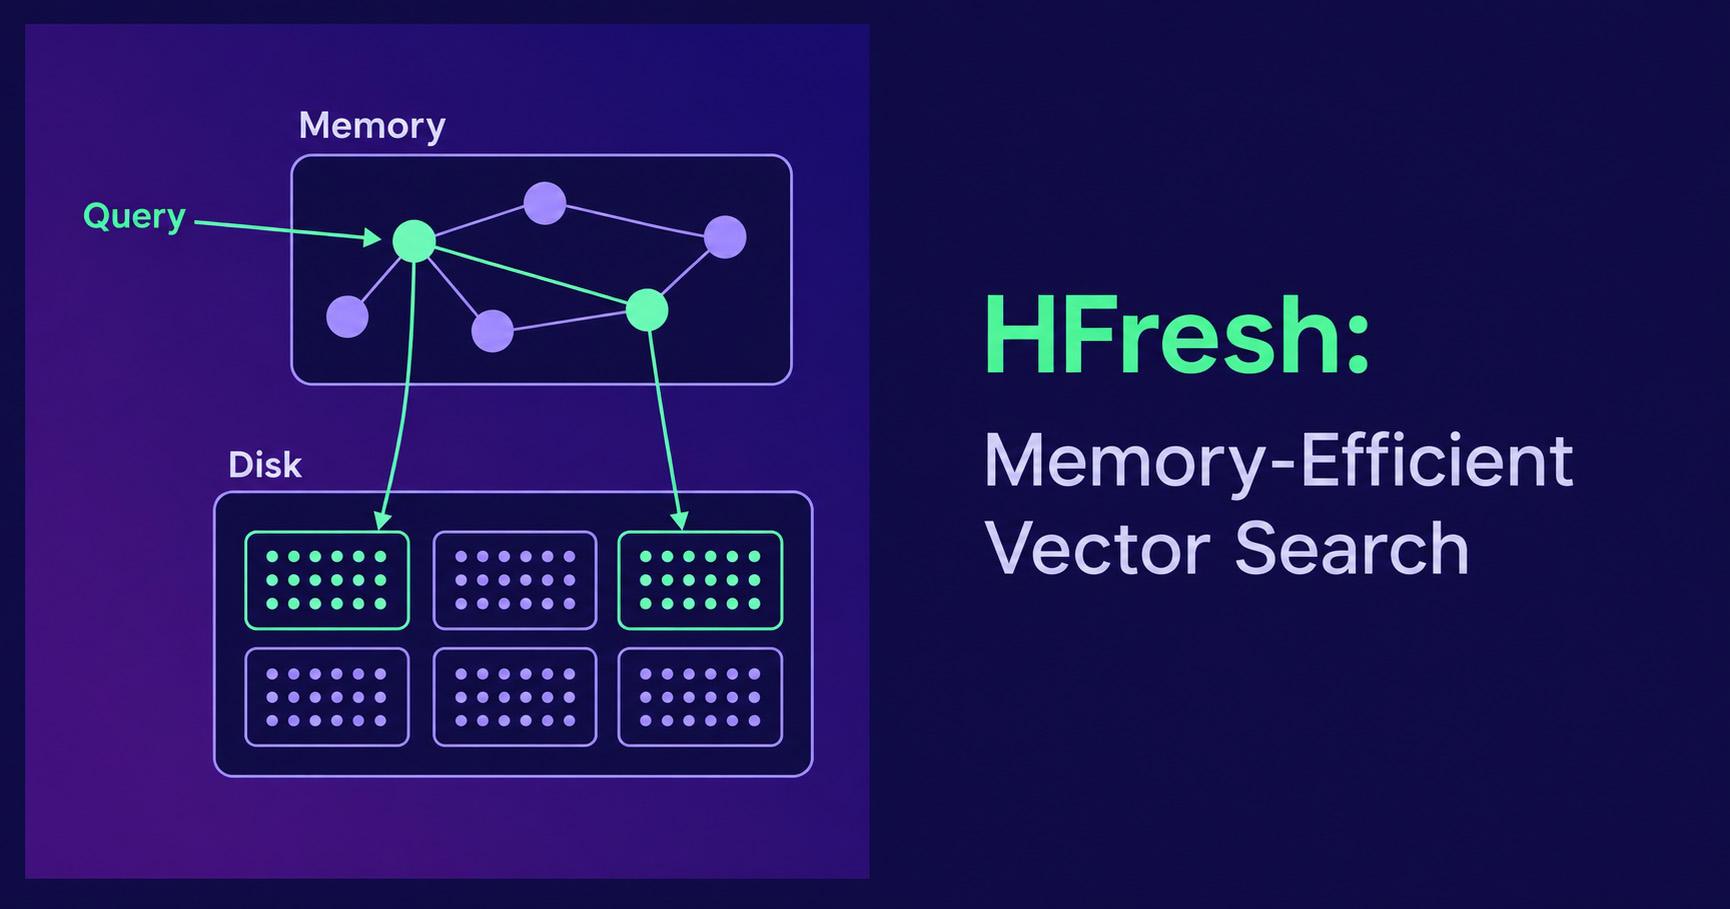
HFresh: Memory-Efficient Vector Search
HFresh is Weaviate's disk-based vector index for memory-efficient vector search, combining low heap usage with incremental background maintenance.

Dev.to · Sam Chen
🔍 RAG & Vector Search
3w ago
Build Semantic Search for Legal Documents with Pinecone and GPT-4
You can build a semantic search system for legal documents by combining Pinecone (a vector database),...

Dev.to · Ayi NEDJIMI
🔍 RAG & Vector Search
⚡ AI Lesson
3w ago
How to Implement Retrieval-Augmented Generation (RAG) with Re-Ranking
Basic RAG retrieves the top-k documents and passes them all to the language model. The problem: those...

Dev.to · SONU OLIKKARA SABU
🔍 RAG & Vector Search
3w ago
I Built an Agentic Hybrid RAG System with FAISS and BM25
I've been learning about Retrieval-Augmented Generation (RAG) and wanted to understand how it...

Dev.to · Halan P Babu
🔍 RAG & Vector Search
3w ago
Building an Agentic Hybrid RAG System with FAISS, BM25, and smolagents
I've been learning about RAG (Retrieval-Augmented Generation) and wanted to understand how it...

Dev.to · Chizee
🔍 RAG & Vector Search
3w ago
Your AI Feature Doesn't Need Pinecone. It Needs pgvector.
pgvector puts the embedding in the same row as everything else about the thing it describes, so a hybrid semantic + relational query is just a single SQL query

Dev.to · Djaouad Frih
🔍 RAG & Vector Search
4w ago
Case Study: Turning Missed Calls into Booked Leads With an AI Receptionist
A case study: how a 24/7 AI receptionist built with Next.js, NestJS and pgvector RAG stopped missed leads, qualified bookings and handed off with context — runn

Dev.to · Malik Rashid
🔍 RAG & Vector Search
4w ago
Web Scraping API for AI Agents and RAG Pipelines
Retrieval quality begins before the embedding model. If your pipeline indexes navigation labels,...

Dev.to · Melvin Sabu
🔍 RAG & Vector Search
4w ago
Building a Hybrid RAG System with FAISS, BM25, and Agentic AI
As part of my AI Engineering journey, I recently worked on a project that helped me understand how...

Dev.to · Gulshan Yadav
🔍 RAG & Vector Search
1mo ago
Why Vector Databases Are Critical for RAG Systems
A practical look at the retrieval layer of RAG — what a vector database actually does, why keyword...
Weaviate Blog
🔍 RAG & Vector Search
1mo ago
Weaviate 1.39 Release
Weaviate 1.39 promotes the Boost API and MMR diversity selection to GA, previews 4-bit Rotational Quantization, and ships an experimental Search REST API.

Dev.to · Neville Kibwanga
🔍 RAG & Vector Search
1mo ago
INTRODUCTION TO RAG (RETRIEVAL AUGMENTED GENERATION)
Intro to RAG (Retrieval Augmented Generation) I first heard of this technology about a...

Dev.to · Jamal
🔍 RAG & Vector Search
1mo ago
# Building a Personal Notes Assistant with RAG, Amazon Bedrock, and Pinecone
Have you ever saved hundreds of digital notes only to spend twenty minutes hunting for one tiny...

Dev.to · Marcus ma
🔍 RAG & Vector Search
⚡ AI Lesson
1mo ago
How to Build an Agentic RAG Pipeline with Real-Time Web Search
Learn how to build an agentic RAG pipeline that combines vector retrieval with real-time web search and returns cited answers.

Dev.to · Jason Lau
🔍 RAG & Vector Search
⚡ AI Lesson
1mo ago
Your RAG Pipeline Doesn't Have an Accuracy Problem - It Has an Evaluation Problem
A team builds a retrieval-augmented chatbot over the company's internal policy documents. In the...

Dev.to · AI Bug Slayer 🐞
🔍 RAG & Vector Search
⚡ AI Lesson
1mo ago
The Overlooked Reason Your RAG Pipeline Keeps Returning Garbage
An honest take on where AI agents, LLMs, and production systems actually are right now -- from someone deep in the space.

Dev.to · Nabeel Hassan
🔍 RAG & Vector Search
⚡ AI Lesson
1mo ago
Your RAG Demo Works Because Someone Picked the Documents
A RAG prototype takes an afternoon. Chunk some documents, embed them, stuff the top matches into a...

Dev.to · Humza Tareen
🔍 RAG & Vector Search
1mo ago
When RAG Says Duplicate but the LLM Disagrees: Building an Adjudication Layer
How I added an LLM second-opinion layer to a RAG deduplication gate, using a two-threshold review band to clear embedding false positives without blocking valid

Dev.to · Maya Andersson
🔍 RAG & Vector Search
⚡ AI Lesson
1mo ago
Dividing your RAG score by retrieval recall overstates your generation quality, and here is by how much
Almost every RAG eval writeup I read, including several I have recommended, uses the same mental...

Dev.to · Derek Mwale
🔍 RAG & Vector Search
1mo ago
Building Semantic Search: From Embeddings to a Production-Ready Search Engine
Search looks simple until you try to build a system that understands what people actually mean. A...

Dev.to · Haroon Ahmad
🔍 RAG & Vector Search
1mo ago
Chunking: the most underrated decision in your RAG pipeline
Ask a team how their RAG pipeline works and they will tell you about the embedding model, the vector...

Dev.to · Dinesh_gowtham
🔍 RAG & Vector Search
1mo ago
ElastiCache for RAG: How to Store and Query Embeddings in Redis with Node.js and TypeScript
You can serve LLM‑powered answers in milliseconds by caching vector embeddings in Redis—no separate...

Dev.to · Ace-2504
🔍 RAG & Vector Search
⚡ AI Lesson
1mo ago
The model had the right evidence. It still got the answer wrong.
I ran a controlled 60-question RAG experiment to find out whether retrieval or the reader was the real bottleneck. The results surprised me.
When Better Retrieval Doesn't Mean Better Answer
When Better Retrieval Doesn't Mean Better Answers. ...
 DeepCamp AI