RStudio for Six Sigma - Process Capability
Key Takeaways
Performs Process Capability Analysis using RStudio for Six Sigma
Original Description
Welcome to RStudio for Six Sigma - Process Capability. This is a project-based course which should take under 2 hours to finish. Before diving into the project, please take a look at the course objectives and structure.
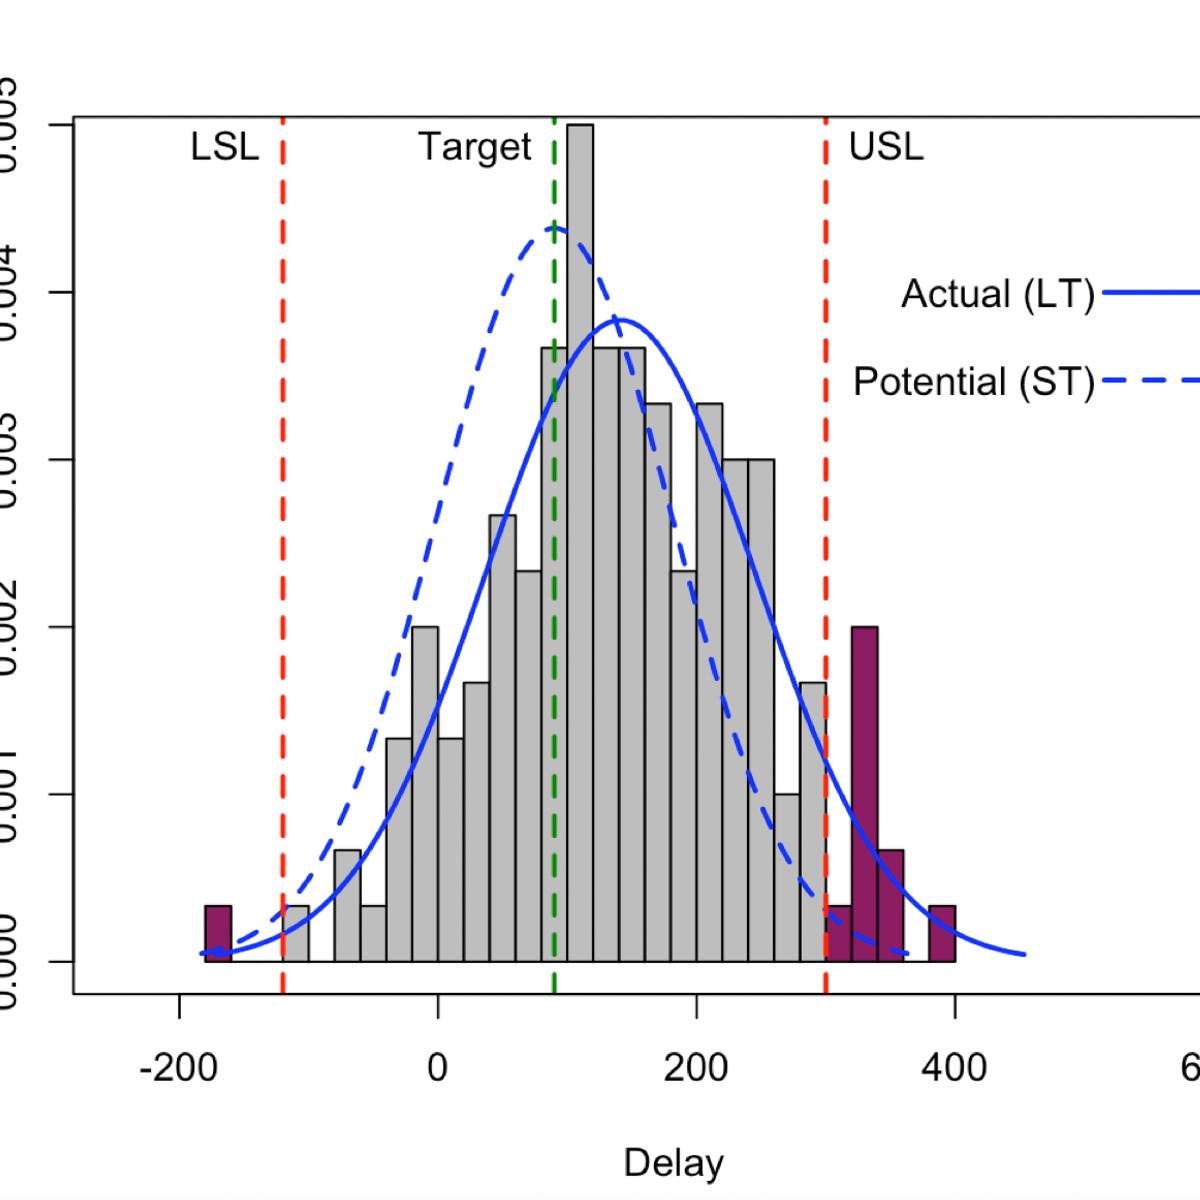
By the end of this project, you will understand the concepts like DPU, DPO and DPMO; learn to import discrete defect data file and perform Process Capability Analysis, understand Throughput Yield and Rolled Throughput Yield (RTY) and calculate RTY for data imported from a file, understand Z score, Short and Longterm Standard Deviation, Short and Longterm Z Bench, Cp, Cpk, Pp, Ppk, and perform Process Capability Analysis for continuous data.
AI explanation not available for this lesson yet
This lesson is still being prepared for the AI tutor. In the meantime, explore lessons that are ready.
Browse explainer-ready lessons →
More on: Data Literacy
View skill →


Related Reads
📰
📰
📰
📰
RL 3: Bellman Equations and Markov Decision Processes (1950s–1960s)
Dev.to AI
New ‘Reinforcement Learning For Calibrated Decisions’ Makes AI Headlines But Look Past The Hype
Forbes Innovation
EvoRS: On-Policy Self-Evolution of Reward Systems for Open-Ended Reinforcement Learning
ArXiv cs.AI
BRACE: Anchored Bellman-Residual Correction for Stale Critics in Asynchronous RL
ArXiv cs.AI
🎓
Tutor Explanation
 DeepCamp AI